-
All Machine Learning Algorithms To Study
All Machine Learning Algorithms To Study Table Of Contents: Regression Algorithms. Classification Algorithms. Clustering Algorithms. Ensemble Learning Algorithms. Dimensionality Reduction Algorithms Association Algorithms. Reinforcement Learning Algorithms. Deep Learning Algorithms. (1) Regression Algorithms Linear Regression. Regression Trees. Non-Linear Regression. Bayesian Linear Regression. Polynomial Regression. LASSO Regression. Ridge Regression. Weighted Least Squares Regression. (2) Classification Algorithms Logistic Regression Decision Trees Random Forest Support Vector Machines K – Nearest Neighbors Naive Bayes Algorithm (3) Clustering Algorithms K-Means Clustering K-Medoids (PAM) Hierarchical Clustering (Agglomerative and Divisive) DBSCAN (Density-Based Spatial Clustering of Applications with Noise) Mean Shift Clustering Gaussian Mixture Models (GMM) Spectral Clustering Affinity
-

Outlier Handling Techniques.
Outlier Detection Techniques Table Of Contents: What Is An Outlier ? Characteristics Of An Outlier. Causes Of Outlier. Why Handle Outliers? Outlier Handling Techniques. Python Examples. (1) What Is An Outlier? An outlier is a data point that significantly deviates from the rest of the dataset. It is unusually large or small compared to other values and may indicate variability, errors, or rare events. (2) Example Of An Outlier. Data Set: 150, 160, 162, 158, 170, 165, 175, 169, 180, 300. In this example, the height 300 cm is an outlier because it is much higher than the other values,
-

Data Cleaning Strategies.
Data Cleaning Strategies Table Of Contents: What Is Data Cleaning? Handling Missing Data. Handling Outliers. Removing Duplicate Data. Standardizing Column Names. Standardizing Data Formats Correct Data Types. Feature Selection. Feature Engineering. Addressing Class Imbalance. Dealing With Multicollinearity. Encoding Categorical Variables. Data Normalization & Standardization. Handling Text Data. Handling Time Series Data. Saving the Cleaned Data. (1) What Is Data Cleaning? In simple terms, data cleaning is the process of fixing or removing incorrect, incomplete, or irrelevant data from a dataset. It ensures that the data is accurate, consistent, and ready for analysis or use in a machine learning model. (2)
-
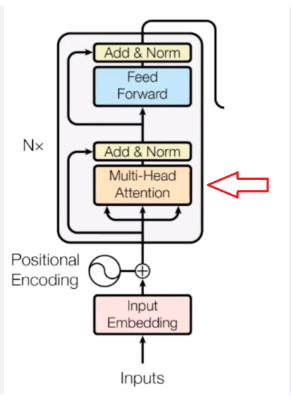
Transformers Neural Networks
Transformers Neural Networks Table Of Contents: What Is Transformer? Key Features Of Transformer? Applications Of Transformer? Key Features Of Transformer? How Do Transformers Handle The Issue Of Vanishing Gradients In Long-Term Dependencies? (1) What Is Transformer? Transformers are a type of deep learning model architecture that have gained significant attention and popularity, particularly in natural language processing (NLP) tasks. Unlike traditional recurrent neural networks (RNNs), transformers rely on a self-attention mechanism to capture dependencies between different elements of the input sequence. (2) Key Features Of Transformer? Self-Attention Mechanism: The self-attention mechanism is the core component of transformers. It allows the
-
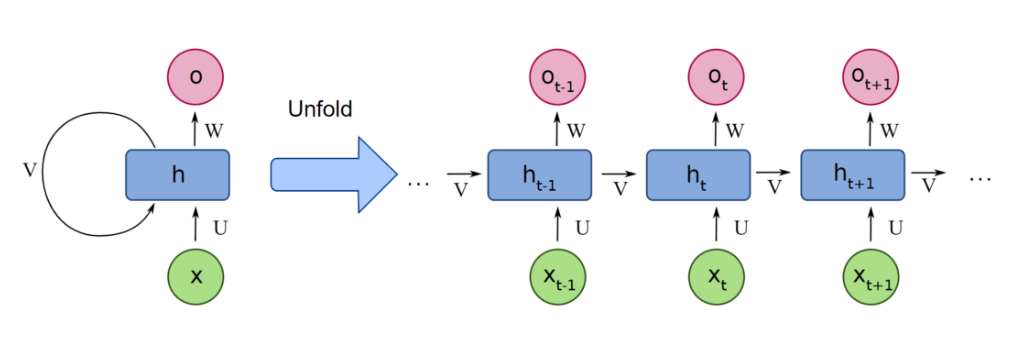
Recurrent Neural Networks(RNN)
Recurrent Neural Networks Table Of Contents: What Is Recurrent Neural Networks? (1) What Is Recurrent Neural Networks? Recurrent Neural Networks (RNNs) are a type of artificial neural network designed to process sequential and time-dependent data. They are particularly effective in tasks involving sequential data, such as natural language processing, speech recognition, time series analysis, and handwriting recognition. The key feature of RNNs is their ability to maintain a hidden state that captures information from previous time steps and propagates it to future steps. This recurrent connectivity allows RNNs to capture temporal dependencies and patterns in the data. (2) Components Of
-

Multi Horizon Forecasting
Multi Horizon Forecasting Table Of Contents: What Is Multi Horizon Forecasting? (1) What Is Multi Horizon Forecasting? Multi-horizon forecasting in time series refers to predicting future values of a time series over multiple future time steps. Instead of making a single-step forecast, where you predict the next value in the time series, multi-horizon forecasting involves predicting several future values at once, typically for a predefined range or sequence of future time steps. For example, in a daily sales forecasting scenario, a single-step forecast would predict tomorrow’s sales based on today’s data. In contrast, a multi-horizon forecast might predict the sales
-

Boosting Algorithms
Boosting Algorithms Table Of Contents: What Is Boosting In Machine Learning? Types Of Boosting Algorithm. (1) What Is Boosting? Boosting is a machine learning ensemble technique that combines multiple weak learners (typically decision trees) to create a strong learner. The main idea behind boosting algorithms is to iteratively train weak models in a sequential manner, where each subsequent model focuses on correcting the mistakes made by previous models. This iterative process gradually improves the overall predictive performance of the ensemble. (2) Types Of Boosting Algorithms. AdaBoost (Adaptive Boosting): AdaBoost assigns weights to each training instance and adjusts them based on
-
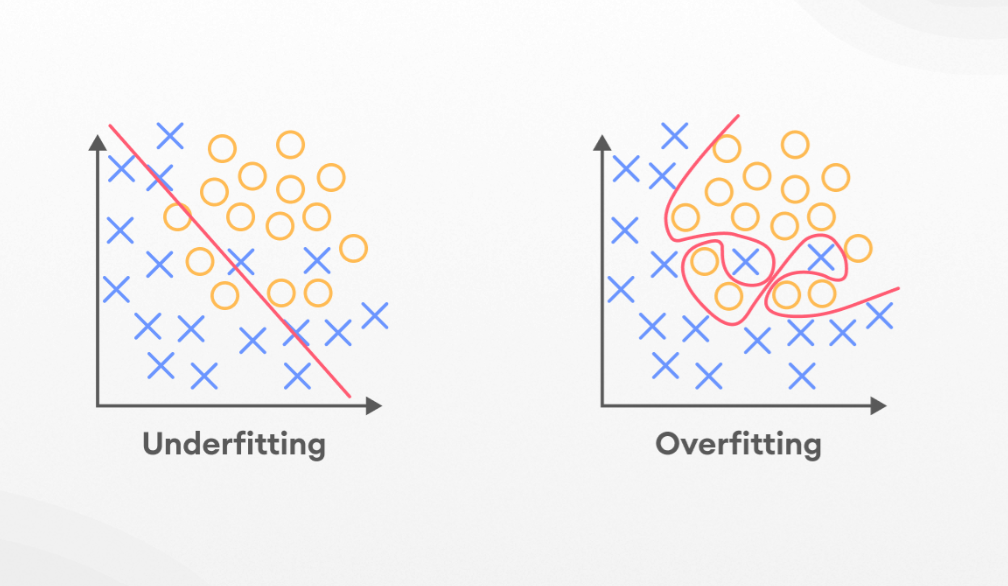
Under Fitting Vs Over Fitting
Underfitting vs Overfitting Table Of Contents: What is Generalization What is Underfitting What is Overfitting How To Detect Underfitting How To Avoid Underfitting How To Detect Overfitting How To Prevent Overfitting Model Prone To Underfitting (1) What Is Generalization? In supervised learning, the main goal is to use training data to build a model that will be able to make accurate predictions based on new, unseen data, which has the same characteristics as the initial training set. This is known as generalization. Generalization relates to how effectively the concepts learned by a machine learning model apply to particular examples that were
-
Bias Vs Variance !!
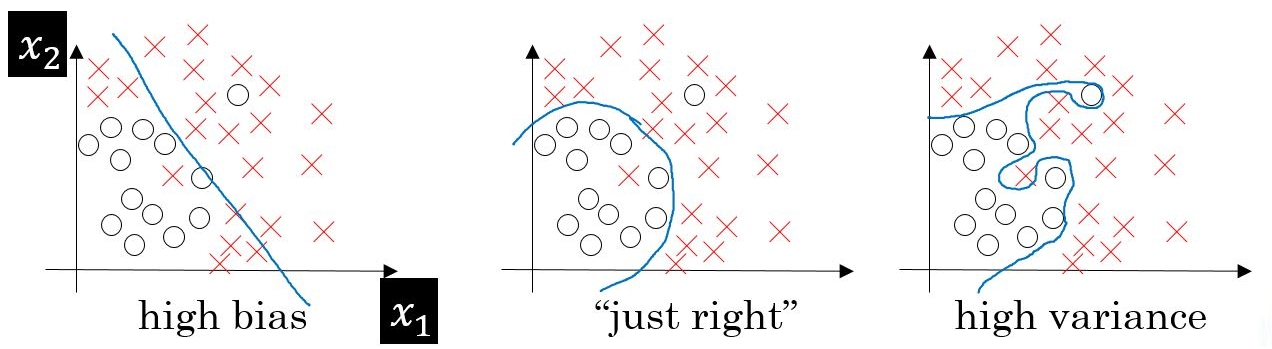
Bias Vs Variance Table Of Contents: Introduction. Errors In Machine Learning. What Is Bias? Why Does Bias Occurs In Model? Effect Of Bias In Our Model. Way To Reduce High Bias. What Is Variance? Why Does Variance Occurs In Model? Effect Of Variance In Our Model. Way To Reduce High Variance. What Is Bias Variance Trade-Off? (1) Introduction. Bias and variance are two important concepts in machine learning that help in understanding the behaviour and performance of a model. They represent different sources of error in a machine learning algorithm and can provide insights into how well the model is
-

Regularization In Machine Learning.
Regularization In Machine Learning Table Of Contents: What Is Regularization? Types Of Regularization Techniques. L1 Regularization (Lasso Regularization). L2 Regularization (Ridge Regularization). Elastic Net Regularization. Why It Is Called Penalty? What Does The Penalty Do Comparison Of L1 and L2 Penalty How to Choose the Regularization Type? Effect of Regularization Parameter (𝜆) Can We Apply Regularization To All The Machine Learning Models ? (1) What Is Regularization? We need a regulator for our model to have control of the learning, we can have control to avoid overfitting of the model. Regularization in machine learning is a technique used to prevent